

Picture two questionnaires about the same dining hall. One asks “Do you like the food?” with yes and no, the other asks “How would you rate the food?” on five steps. The first splits the room, the second shows how far apart people really are.
A rating question is the question type that measures attitudes, opinions and self-reported behavior in steps: you put a statement or a question in front of your respondents and they answer it on a graded scale, with words, with numbers or with symbols. We show you the three rating formats you can choose from and the four rules that keep the answers worth reporting.
📌 The key points at a glance
- A rating question measures degrees instead of yes or no.
- Verbal, numeric and visual are the three rating formats.
- The question is the wording, the rating scale the response format.
- Pew warns against questions that cover two concepts at once.
- Without an open follow-up you never learn the reason.
Create a survey for free
With empirio.ai you can create a modern online survey in minutes — free to start.
- AI-built survey
- Adjust by drag & drop
- Real-time analysis
What is a rating question?
A rating question is a question type for measuring attitudes, opinions and behavior. Respondents get a statement or a question and judge it on a scale with several steps, for example from “very satisfied” to “very dissatisfied.”
Among the question types in a survey the rating question belongs to the closed-ended formats. Lenzner and Menold (2015) sort response formats into three groups in the GESIS Survey Guidelines: open-ended questions, closed-ended questions with rating scales and closed-ended questions without them. A rating question works with the second group.
One note on the label itself, because it saves time when you research. “Rating question” is mostly a practitioner’s term. Methods literature usually names the response format and talks about rating scales. Search for that phrase and you will find far more solid material than under the everyday word.
Rating question and rating scale: where the difference lies
The rating question is the wording, the rating scale is the response format underneath it. Both belong together and are still decided separately: the wording sets what gets rated, the scale sets in which steps people may rate. How many steps you need, whether the scale has a midpoint and how you label the steps are therefore separate decisions.
Plenty of overviews online mix the two and list nothing but scale variants under “rating questions.” What counts is the combination. A well-built scale cannot rescue an unclear question and a precise question is no help when the steps do not fit it. This article deals with the question side.
The scale decides how finely you measure. The question decides what you measure.
What you are allowed to calculate from the answers
Answers to a rating question sit on an ordinal scale, strictly speaking. The steps come in a clear order, but nobody can show that the gap between “good” and “fair” is as large as the gap between “fair” and “poor.” You often read that rating questions sit at interval level and that the mean is therefore fine. That is not a property of the data, it is an assumption.
So the mean is defensible only when you state the assumption of equal distances and justify it. As a rule: for a single rating question, the frequency distribution and the median are the safer choice. Only when several statements on the same topic are combined into one score, as is usual with the Likert scale, does the mean become standard, and even then equal distances stay an assumption that belongs in your methods section.
Which rating formats can you use in a questionnaire?
Three rating formats cover almost everything a rating question needs: the steps carry words, they carry numbers or they carry pictures. What respondents see on screen has a say in how carefully they answer and how well you can read the answers afterward.
The choice is not a matter of taste. Words leave the least room for misreading, numbers only work with systems your audience already knows, and pictures collect answers where words get in the way. Let us go through the three one at a time.
Verbal rating: one word per step
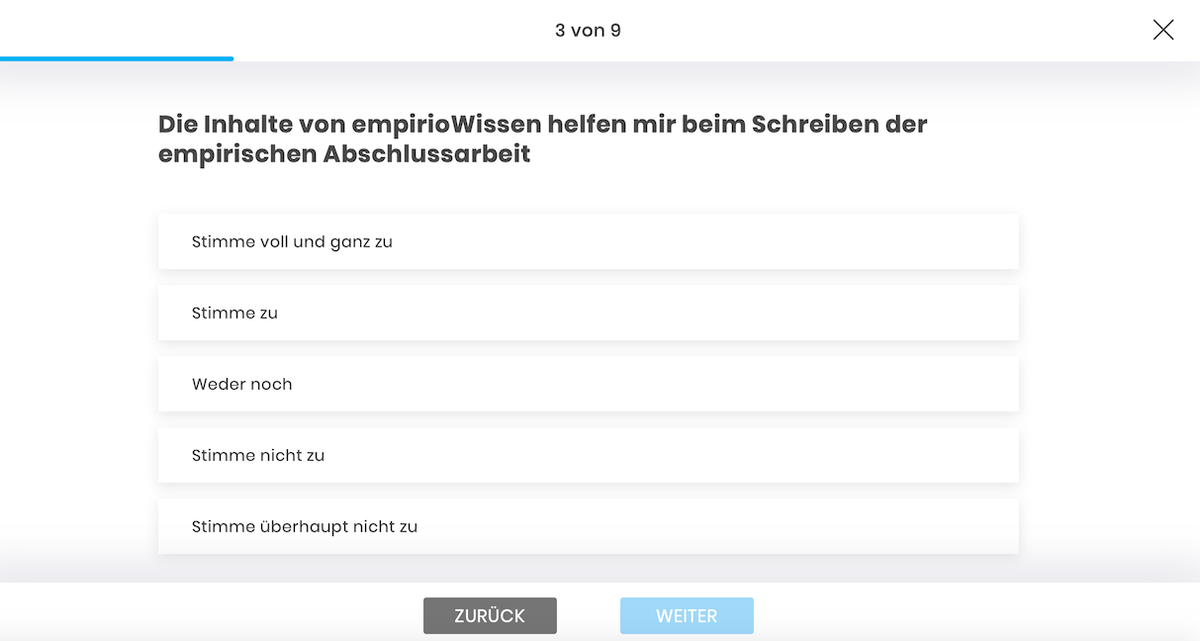
With a verbal rating every step carries its own wording, for example “does not apply at all,” “applies a little,” “applies in part,” “applies quite a lot” and “applies completely.” Fully labeled steps are common in academic questionnaires, because nobody has to guess what a step means. The price is space: beyond seven steps you will barely find words whose distances still feel even.
Numeric rating: numbers instead of words
With a numeric rating, numbers stand in for the steps, usually 1 to 5 or 0 to 10. That works when the range is short and both ends carry a word. With a bare number scale from 1 to 7 and no labels it is the other way around: two people read the same number differently and the data never tells you.
School grades are no shortcut in the United States, because grades here are letters. The ladder runs A, B, C, D and F, with no E between D and F, and on the 4.0 scale an A is worth 4.0 while an F is worth 0.0, as the grading scale at UNC-Chapel Hill sets out. Other grading traditions are numeric and they disagree about which end is the good one: German school marks run from 1 to 6 and 1 is the best. So a bare 1 to 6 carries no shared meaning for a mixed sample, and you label at least both ends with words.

One special case of the numeric rating has grown into a standard of its own. The Net Promoter Score works with a range from 0 to 10 where usually only the two ends carry a word, and it combines the answers into a single figure by a fixed rule.
Tip
Already asked the recommendation question? You don't have to sort the answers into groups yourself. Enter them in our calculator to calculate the NPS, along with the share of promoters and detractors.
Visual rating: symbols, stars, smileys
With a visual rating, pictures take over the steps: stars, smileys, thumbs or icons. Their strength shows where reading slows people down: with children, with quick feedback after an appointment and in surveys that cross language borders. Their weakness is interpretation, because one smiling face means “good” to one person and “very good” to the next.

For a thesis or a capstone project, a visual rating is rarely the first choice. For a club cookout or a comment card at the counter, it is often the only one that gets answered at all.
Note for your methods section
Symbols and smileys have no meaning that language has fixed. That makes it hard to justify which number sits behind which picture. If you use a symbol rating in academic work, show the symbols in the appendix and report the frequencies per step rather than a mean.
Where rating questions are used
Rating questions come into play whenever respondents are meant to give a subjective judgment and a yes or no would be too coarse. In sociology and psychology they are basic equipment, and in market and opinion research they shape a large part of the questionnaires.
What these fields share is an act of translation. Feelings, attitudes and satisfaction do not exist as numbers, and a rating question turns them into graded categories you can count afterward.
Four fields show up especially often in practice:
- Satisfaction: with a product, a workshop, a club
- Self-assessment: your own nerves, skills or workload
- Judging others: a teacher rates a class, a team rates its leadership
- Importance: how much single criteria matter to your respondents
At universities, course evaluations are the best-known case and they show how closely wording and purpose hang together. Statements like “The course was well structured” get rated in steps there, because a step carries more information than a yes or no and because the same form keeps results comparable across several semesters. In companies the same pattern runs under measuring employee satisfaction.
How to write a rating question: four rules from survey research
Plenty of useless ratings are not caused by the scale but by the line above it. When a question addresses two things at once or leaves open what it refers to, respondents still check a box. Afterward nobody knows what they meant.
For this part of the job there are well documented recommendations. Rolf Porst bundled his advice into ten commandments of question wording (Porst 2000, ZUMA How-to series no. 2, in German) and points out himself that they are not iron laws. The GESIS Survey Guidelines on question wording by Lenzner and Menold (2015, also in German) explain why such slips overload respondents. For a source in English, the Pew Research Center keeps a methods page on writing survey questions. Four rules decide almost everything about rating questions.
Rule 1: One issue per question, not two
Porst sums this up in his fourth commandment, paraphrased here from the German: avoid double stimuli and negations. Pew calls a question that asks people to evaluate more than one concept double-barreled and writes that such questions “are difficult for respondents to answer and often lead to responses that are difficult to interpret.” Ask people to rate advising and opening hours in one question, and everyone who likes one and dislikes the other hands you an answer that means nothing.
Rule 2: No negation and no assumption in the wording
Negations are especially expensive in rating questions, because the scale underneath has a direction. Lenzner and Menold advise against words like “not” or “no” in questions, paraphrased from their German text, because such words are easy to overlook. Pew also tells you to avoid double negatives and unfamiliar jargon: “In general, questions that use simple and concrete language are more easily understood by respondents.”
Porst’s fifth commandment adds assumptions and leading questions to the list. “How much did you like the new layout?” already takes for granted that you liked it, and the scale underneath cannot repair that.
Rule 3: A clear frame of reference, in subject and in time
A rating needs an object and a period, otherwise everyone rates something different. Porst asks for questions with a clear time reference and lists concrete dates instead of vague words like recently, paraphrased here from the German. Lenzner and Menold show the same with an example, in paraphrase: a question about whether someone saw a doctor recently becomes a question about the last four weeks.
For rating questions that means “How would you rate the advising you got last semester?” instead of “How would you rate the advising?”
Rule 4: Wording and response steps have to match
The steps under the question have to show exactly the dimension you asked about. A question about satisfaction gets satisfaction steps, a question about frequency gets frequency steps. Sounds obvious and happens all the time: under “How important is a quick reply to you?” you will often find steps from “strongly agree” to “strongly disagree.”
Pew treats those agree-disagree formats with care anyway, because less informed respondents tend to agree, and offers a choice between two alternative statements instead. What else response options have to deliver is in our piece on closed-ended questions.
| Problem in the wording | Not like this | Better |
|---|---|---|
| Double-barreled | How do you rate advising and opening hours? | two separate rating questions |
| Negation | The course was not too fast. | How do you rate the pace of the course? |
| Assumption | How much did you like the new layout? | How do you rate the new layout? |
| No time frame | How do you rate the advising? | How do you rate the advising this semester? |
One check is left that no rule book replaces. Read your rating question out to someone who does not know the topic and ask what they think they are rating. If the answer differs from your intention, the question is the problem. Where such a test run belongs in the process is in our guide to creating a questionnaire.
Create a survey for free
With empirio.ai you can create a modern online survey in minutes — free to start.
- AI-built survey
- Adjust by drag & drop
- Real-time analysis
Rating or criticism? Why a follow-up question belongs with it
A rating question tells you where things stand and never why. It hands you a step but no reason: whether someone rates the dining hall “poor” because the food was cold, because the line is too long or because prices went up, the step they checked does not say.
So plan an open follow-up for every rating question whose result is supposed to lead to a decision. Who actually gets to see it is a second step. That is one more field in your questionnaire and it usually brings you more than a second scale. How to turn those text answers into countable categories is in our piece on open-ended questions.
Asking for criticism on purpose, by the way, is something different from collecting a bad rating. If you want to know what someone would change, ask about the change rather than the grade: “What should we change about the workshop first?” brings concrete suggestions, while a scale from “very good” to “very poor” only records how satisfied someone is.
Tip
Show the follow-up only where it pays off. People who pick one of the two bottom steps get “What was the main reason for your rating?” People who pick one of the two top steps get “What helped you most?” That keeps the questionnaire short and you get text exactly from the people whose answer moves you forward.
Conclusion
A rating question takes a minute to put in a questionnaire and is devalued just as fast. One issue per question, a clear time frame and response steps that fit what you asked will do more for you than any extra step on the scale. And if the why matters to you, plan the open field in from the start, because people who have already voted are hard to ask for a reason afterward.
What to read next
- Still deciding on steps and a midpoint? Rating scale: steps, labels and the midpoint
- Working with several statements on one topic? Likert scale
- Unsure about the level of measurement? Levels of measurement
- Answers already in? How to evaluate a questionnaire
Want to see your rating question in a real questionnaire before it goes out?
With empirio.ai, an online survey tool from Germany, you set up a graded rating question in a few minutes and check after a handful of test answers whether the distribution gives you what you want to report.