

A statistics exam has twenty questions, but only seven of them cover the material taught in the lectures. The marks come out low. What that exam measured was not what students learned during the term, it was what they already knew beforehand.
Validity is the extent to which a measurement captures what it is meant to capture: a questionnaire, a test or an exam is valid when it measures the characteristic named in the research question and not, unnoticed, a different one, because only then do the results answer the question you actually asked. By the end of this article you will be able to say which type of validity your own study can claim.
📌 The key points at a glance
- Validity means the measurement captures the intended characteristic.
- Content, criterion and construct validity are the three types.
- No single coefficient reports validity.
- Internal validity concerns causal claims, external validity generalisation.
- Ofqual calls reliability a necessary condition of validity.
Create a survey for free
With empirio.ai you can create a modern online survey in minutes — with hosting in the EU.
- AI-built survey
- Adjust by drag & drop
- Real-time analysis
Validity in one sentence: measuring the right thing
Validity is the extent to which a measurement captures the characteristic it is supposed to capture. Moosbrugger and Kelava (2012) put it plainly: a test is valid when it really measures the characteristic it is meant to measure and not some other one.
Alongside objectivity and reliability, validity forms the third of the main quality criteria in quantitative research. Unlike the other two it does not depend on how an enquiry is run but on how it was designed. A survey administered faultlessly can still measure beside the point, and no coefficient will show it.
Valid is the adjective. Back to the exam: if the questions come from an older syllabus and only a third of them match the material actually taught, the exam is not valid. The instrument captures something other than what it should, and the mark says little about what was learned.
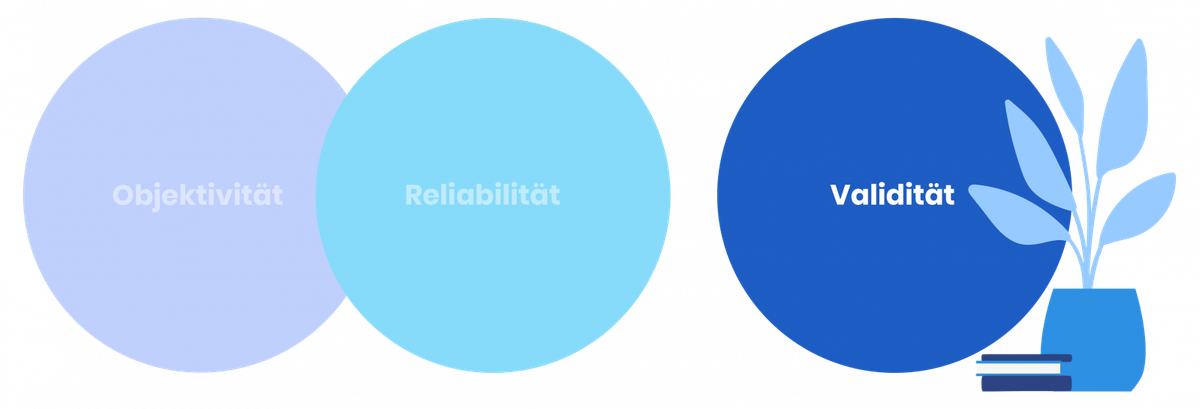
Validity presupposes reliability, and only in that direction. Moosbrugger and Kelava state that a test with low reliability cannot have high validity. A precise measurement may still miss the point, an imprecise one can never be valid.
Note
In everyday use, valid means something like sound or defensible, as in „valid figures“. As a quality criterion the word is narrower: a measurement is valid only in relation to a specific characteristic and a specific purpose, never in general.
How the UK regulator defines validity
Ofqual sets out validity as a regulatory condition, not as a textbook concept. Condition D1.2 of the Ofqual Handbook defines it as „the extent to which evidence and theory support the interpretation that the assessment outcomes meet their intended uses“. Validity, in other words, attaches to the interpretation of results and not to the paper itself.
The same condition names five criteria in a fixed order: Validity, Reliability, Comparability, Manageability and Minimising Bias. Objectivity does not appear among them. Anyone arriving from German-language methodology literature, where objectivity is one of three headline criteria, will not find its counterpart in UK regulation.
Ofqual also spells out a ranking that textbooks often leave implicit: „Reliability is a necessary condition of Validity, as it is not possible to demonstrate the Validity of an assessment process which is not Reliable.“ For a dissertation that means reporting the accuracy of your scales before arguing that they measure the right thing.
A second habit worth borrowing from the regulator: Ofqual expects a validity argument, built from statements of the proposed interpretation together with supporting evidence gathered across the whole assessment process. A methodology chapter that argues in that shape reads far better than one that asserts validity in a single line.
Three types of validity and how each one is evidenced
Validity is not established by a single procedure. Evidence for it comes from different directions, and test theory sorts that evidence into three types. What separates them is the yardstick: the content of the instrument itself, an external criterion, or the theory behind the characteristic.
For a dissertation the choice is usually quick. An independent external criterion is rarely available, so content validity and construct validity carry the methodology chapter, and both are argued rather than calculated.
Content validity: does the questionnaire cover the characteristic?
Content validity indicates how representatively a test, or a single item, captures the characteristic being measured. Nothing is calculated here. The evidence comes from the subject-matter reasoning behind each item and from a formal rating in which several experts judge relevance, representativeness, specificity and clarity. The GESIS survey guideline on validity recommends exactly that rating before a scale is used.
Criterion validity: can you infer something outside the test?
Criterion validity exists when behaviour inside the test situation supports an inference to a criterion outside it. A criterion available at the same time gives concurrent validity, a future one gives predictive validity. An admissions test whose score relates to later academic performance has predictive validity. A criterion is always an independently measured characteristic and never a second piece of literature on the same topic.
Construct validity: does the inference to the underlying characteristic hold?
Construct validity exists when the inference from response behaviour to the underlying characteristic is scientifically founded. Evidence runs in two directions: high correlations with instruments measuring the same thing (convergent validity) and low correlations with instruments measuring something deliberately different (discriminant validity). Modern test theory treats construct validity as the umbrella over all types of evidence rather than as one type among three.
Older lists name five types, adding expert validity and known-groups validity. Neither is a type of its own: both are routes to evidencing the first three. An expert judgement supports content validity, and a comparison with a group whose difference is known in advance supports construct validity. Keeping that straight matters, because otherwise procedures and types of validity end up in one undifferentiated list.
Internal and external validity: two questions about the design
Internal and external validity assess the study design rather than the measuring instrument. Internal validity asks whether a claim about cause and effect holds inside the study, that is whether the variable under investigation really produced the effect and not some third factor. External validity asks how far the findings travel: do they hold for other groups of people, other settings and other points in time? Lydia Repke, Lukas Birkenmaier and Clemens M. Lechner separate the two in the GESIS survey guideline on validity (2024).
Internal and external validity pull in opposite directions. The guideline records that scholars commonly assume the two to be inversely related, without that making the tension inevitable. A laboratory experiment keeps confounders out and everyday life with them. A field survey lets everyday life in, together with every influence nobody controls.
For an online survey the dividing line is clear. External validity rests on the sample, internal validity on whether alternative explanations can be ruled out. A study of 80 coursemates that ends up making a claim about all students in the UK has a problem with reach, not with the questionnaire. The research design you choose therefore decides which of the two you can claim at all.
Create a survey for free
With empirio.ai you can create a modern online survey in minutes — with hosting in the EU.
- AI-built survey
- Adjust by drag & drop
- Real-time analysis
Why there is no validity coefficient to report
Test theory has no counterpart to the reliability coefficient. Validity is not reported as a number in the results chapter, it is argued in the methodology chapter, and only part of that argument can be calculated at all. Looking for the range of values for validity means looking for something that does not exist.
Criterion validity can be calculated, because it is the correlation between a test score and a criterion. For reading such correlations the GESIS survey guideline offers rough benchmarks: small (0.10), medium (0.30) and large (0.50). Those numbers are a reading aid for correlations, not a threshold for validity.
| Type | Evidence | Fits when |
|---|---|---|
| Content validity | subject-matter reasoning and expert rating | almost every dissertation |
| Construct validity | correlations with similar and dissimilar instruments | you built the scale yourself |
| Criterion validity | correlation with an independent criterion | an external criterion exists |
| Internal validity | control of alternative explanations | experiments and causal questions |
| External validity | sampling and survey setting | claims about a population |
Careful
Never report a validity figure you have not calculated yourself. In a viva the methodology is defended, not the coefficient: reasoned content validity plus an openly stated limit of your sample carries far more weight than a number with no procedure behind it.
Improving validity: what gets decided before fieldwork
Validity is decided during operationalisation, at the moment an abstract concept turns into concrete questions. After fieldwork nothing can be repaired: a question that misses the characteristic keeps missing it, however many responses arrive.
The single most effective step is a pilot. Five to ten people from the target group complete the questionnaire and then describe how they understood each question. Where the intended meaning and the understood meaning come apart, validity is lost, and no coefficient will flag it.
Two confusions cost marks in methodology chapters again and again. The first concerns Cronbach's alpha: a high value evidences accuracy and not validity. A scale can be perfectly consistent and still capture social desirability instead of an actual attitude. The second concerns the criterion: comparing your own survey results with the literature checks how plausible your findings are, not the criterion validity of your instrument.
What keeps your measurement valid
- The hypothesis exists before the first question.
- Every question belongs to a dimension of the research question.
- Several questions approach the same characteristic from different angles.
- A pilot shows how the target group reads each question.
- Experts review the item pool before you send it out.
- The limits of the sample appear in the methodology chapter.
Conclusion
Of the three quality criteria, validity looks the least like statistics and says the most about a piece of research. It is argued rather than calculated, and the argument is built while the questions are being written. Anyone who keeps the three types apart and states the reach of their sample openly walks into the viva on solid ground.
No number evidences validity. The reasoning behind the questions does.
Where to go next
- Want all three quality criteria side by side? Objectivity, reliability and validity compared
- Need the accuracy of a measurement? What does reliability mean?
- Looking for the third criterion? What does objectivity mean?
- Want to justify your sample? When is an online survey representative?
- Want the whole process in view? Empirical research: definition, methods, guide
Our reading tip: for UK practice, Section D of the Ofqual Handbook defines all five regulatory criteria on one page, including the ranking of reliability and validity. For the types of validity, chapter 2 of Moosbrugger, Helfried and Kelava, Augustin (eds.) (2012): Testtheorie und Fragebogenkonstruktion, 2nd edition, Springer, is freely available as a sample chapter.
Want to pilot your questions before fieldwork starts?
With empirio.ai, an online survey tool from Germany, you build your questionnaire for free and send it to a handful of people first. Data is hosted entirely in the EU.