

Ask ten researchers what validity means and most will answer that an instrument measures what it claims to measure. The Standards for Educational and Psychological Testing say something slightly different, and the difference changes how a methods chapter should be written.
Validity is the extent to which evidence and theory support an interpretation of scores for a proposed use: a questionnaire is valid when the reading you take from its answers really concerns the characteristic in your research question and not, unnoticed, a different one. By the end of this article you will be able to say which kind of validity evidence your own study can offer.
📌 The key points at a glance
- Validity means the measurement captures the intended characteristic.
- Content, criterion and construct validity are the three types.
- No single coefficient reports validity.
- Internal validity concerns causal claims, external validity generalization.
- The 2014 Standards speak of validity evidence, not types.
Create a survey for free
With empirio.ai you can create a modern online survey in minutes — free to start.
- AI-built survey
- Adjust by drag & drop
- Real-time analysis
Validity in one sentence: measuring the right thing
Validity is the extent to which a measurement captures the characteristic it is supposed to capture. Moosbrugger and Kelava (2012) put it plainly: a test is valid when it really measures the characteristic it is meant to measure and not some other one.
Alongside objectivity and reliability, validity forms the third of the main quality criteria in quantitative research. Unlike the other two it does not depend on how an enquiry is run but on how it was designed. A survey administered faultlessly can still measure beside the point, and no coefficient will show it.
Valid is the adjective. Back to the exam: if the questions come from an older syllabus and only a third of them match the material actually taught, the exam is not valid. The instrument captures something other than what it should, and the grade says little about what was learned.
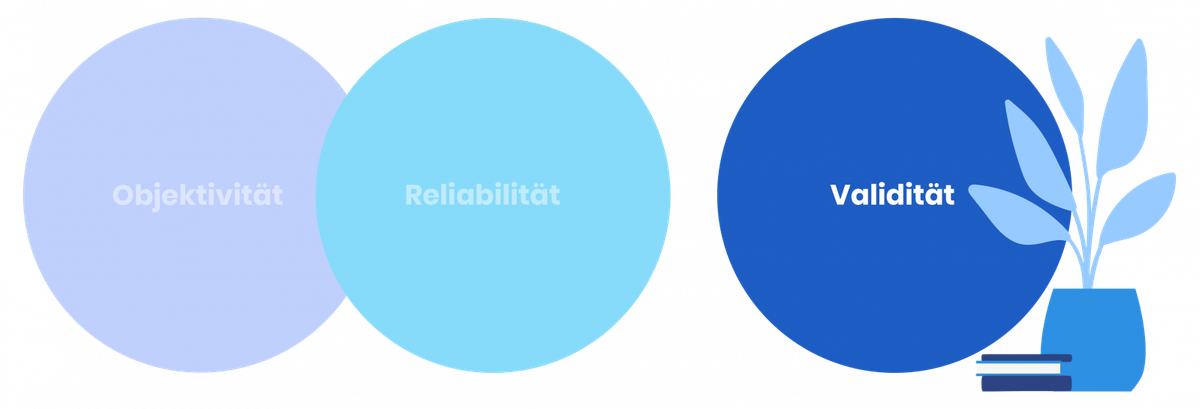
Validity presupposes reliability, and only in that direction. Moosbrugger and Kelava state that a test with low reliability cannot have high validity. A precise measurement may still miss the point, an imprecise one can never be valid.
Note
In everyday use, valid means something like sound or defensible, as in „valid figures“. As a quality criterion the word is narrower: a measurement is valid only in relation to a specific characteristic and a specific purpose, never in general.
How the US Standards define validity
The Standards for Educational and Psychological Testing, published in 2014 by AERA, APA and NCME, define validity as „the degree to which evidence and theory support the interpretations of test scores for proposed uses of tests“. One sentence later the Standards draw the consequence: „It is the interpretations of test scores for proposed uses that are evaluated, not the test itself.“
That wording shifts the object of judgement. A questionnaire is not valid or invalid on its own, a particular reading of its scores for a particular purpose is what carries or fails. Writing „my instrument is valid“ in a methodology chapter therefore claims more than the Standards allow.
The Standards also reorganize the vocabulary. Part I names three foundations, validity, reliability and precision, and fairness in testing, and objectivity is not among them. On the types, the 2014 edition is explicit: it „refers to types of validity evidence, rather than distinct types of validity“, and the four sources it lists are test content, response processes, internal structure, and relations to other variables.
US federal law has not followed that move, which is why both vocabularies circulate side by side. The Uniform Guidelines on Employee Selection Procedures at 29 CFR Part 1607 still allow employers to rely on „criterion-related validity studies, content validity studies or construct validity studies“. Both sources are authoritative and both are current, so a thesis is on safe ground naming the three study types while noting that the Standards prefer to speak of evidence.
Three types of validity and how each one is evidenced
No single procedure settles validity. Support for it accumulates from different directions, and the older three-way vocabulary sorts that support by yardstick: the content of the instrument, an outside criterion, or the theory behind the characteristic.
In graduate work the choice narrows quickly. An independent outside criterion is seldom at hand, which leaves content and construct validity to carry the methods chapter, and both are argued in prose rather than computed.
Content validity: does the questionnaire cover the characteristic?
Content validity indicates how representatively a test, or a single item, captures the characteristic being measured. Nothing is calculated here. The evidence comes from the subject-matter reasoning behind each item and from a formal rating in which several experts judge relevance, representativeness, specificity and clarity. The GESIS survey guideline on validity recommends exactly that rating before a scale is used.
Criterion validity: can you infer something outside the test?
Criterion validity exists when behavior inside the test situation supports an inference to a criterion outside it. A criterion available at the same time gives concurrent validity, a future one gives predictive validity. An admissions test whose score relates to later academic performance has predictive validity. A criterion is always an independently measured characteristic and never a second piece of literature on the same topic.
Construct validity: does the inference to the underlying characteristic hold?
Construct validity exists when the inference from response behavior to the underlying characteristic is scientifically founded. Evidence runs in two directions: high correlations with instruments measuring the same thing (convergent validity) and low correlations with instruments measuring something deliberately different (discriminant validity). Modern test theory treats construct validity as the umbrella over all types of evidence rather than as one type among three.
Older lists name five types, adding expert validity and known-groups validity. Neither is a type of its own: both are routes to evidencing the first three. An expert judgement supports content validity, and a comparison with a group whose difference is known in advance supports construct validity. Keeping that straight matters, because otherwise procedures and types of validity end up in one undifferentiated list.
Internal and external validity: two questions about the design
Internal and external validity assess the study design rather than the measuring instrument. Internal validity asks whether a claim about cause and effect holds inside the study, that is whether the variable under investigation really produced the effect and not some third factor. External validity asks how far the findings travel: do they hold for other groups of people, other settings and other points in time? Lydia Repke, Lukas Birkenmaier and Clemens M. Lechner separate the two in the GESIS survey guideline on validity (2024).
Internal and external validity pull in opposite directions. The guideline records that scholars commonly assume the two to be inversely related, without that making the tension inevitable. A laboratory experiment keeps confounders out and everyday life with them. A field survey lets everyday life in, together with every influence nobody controls.
In an online survey the split is easy to locate. External validity rides on the sample, internal validity on whether competing explanations can be eliminated. Surveying 80 classmates and then writing about students across the United States is a reach problem and not a questionnaire problem. Your research design therefore fixes in advance which of the two is even available to you.
Create a survey for free
With empirio.ai you can create a modern online survey in minutes — free to start.
- AI-built survey
- Adjust by drag & drop
- Real-time analysis
Why there is no validity coefficient to report
There is no counterpart to the reliability coefficient. Nobody reports a validity number in a results table, because the case for validity lives in the methods chapter and only a slice of it is computable. Searching for the range of values for validity is therefore a search for something that was never defined.
Criterion-related evidence is the computable slice, since it takes the form of a correlation between score and criterion. For reading such correlations the GESIS survey guideline offers rough benchmarks: small (0.10), medium (0.30) and large (0.50). Treat them as a reading aid for correlations and never as a pass mark for validity.
| Type | Evidence | Fits when |
|---|---|---|
| Content validity | subject-matter reasoning and expert rating | almost every thesis |
| Construct validity | correlations with similar and dissimilar instruments | you built the scale yourself |
| Criterion validity | correlation with an independent criterion | an external criterion exists |
| Internal validity | control of alternative explanations | experiments and causal questions |
| External validity | sampling and survey setting | claims about a population |
Careful
Never report a validity figure you have not calculated yourself. At a dissertation defense the methodology is defended, not the coefficient: reasoned content validity plus an openly stated limit of your sample carries far more weight than a number with no procedure behind it.
Improving validity: what gets decided before fieldwork
Validity is decided during operationalization, at the moment an abstract concept turns into concrete questions. After fieldwork nothing can be repaired: a question that misses the characteristic keeps missing it, however many responses arrive.
The single most effective step is a pretest. Five to ten people from the target group complete the questionnaire and then describe how they understood each question. Where the intended meaning and the understood meaning come apart, validity is lost, and no coefficient will flag it.
Two confusions cost marks in methodology chapters again and again. The first concerns Cronbach's alpha: a high value evidences accuracy and not validity. A scale can be perfectly consistent and still capture social desirability instead of an actual attitude. The second concerns the criterion: comparing your own survey results with the literature checks how plausible your findings are, not the criterion validity of your instrument.
What keeps your measurement valid
- The hypothesis exists before the first question.
- Every question belongs to a dimension of the research question.
- Several questions approach the same characteristic from different angles.
- A pretest shows how the target group reads each question.
- Experts review the item pool before you send it out.
- The limits of the sample appear in the methodology chapter.
Conclusion
Validity is the quality criterion that looks least like statistics and reveals most about a study. Nobody computes it, everybody has to argue it, and the argument gets built while the items are being written rather than after the data arrive. Keep the kinds of evidence apart, state the reach of your sample plainly, and the defense holds.
No number evidences validity. The reasoning behind the questions does.
Where to go next
- Want all three quality criteria side by side? Objectivity, reliability and validity compared
- Need the accuracy of a measurement? What does reliability mean?
- Looking for the third criterion? What does objectivity mean?
- Want to justify your sample? When is an online survey representative?
- Want the whole process in view? Empirical research: definition, methods, guide
Our reading tip: for US practice, chapter 1 of the Standards for Educational and Psychological Testing (AERA, APA and NCME, 2014) is the reference text and is available as a free download. For the types of validity, chapter 2 of Moosbrugger, Helfried and Kelava, Augustin (eds.) (2012): Testtheorie und Fragebogenkonstruktion, 2nd edition, Springer, is freely available as a sample chapter.
Want to pretest your questions before data collection starts?
With empirio.ai, an online survey tool from Germany, you build your questionnaire for free and send it to a handful of people first. Data is hosted entirely in the EU.